Category

AI Deep Dives & Tutorials

Detailed breakdowns, step-by-step guides, and video demos that show how to create content with AI and where to apply new tools.

179 articles • Page 1 of 12

How "AI Interviewer" Prompts Cut Errors, Improve Task Completion

How "AI Interviewer" Prompts Cut Errors, Improve Task Completion

Interview-style prompts for AI systems start with a simple request and let the AI ask follow-up questions to gather all needed details. This method may cut errors by making the model clarify ambiguous points and check facts step by step. Some studies suggest that guided questioning improves both task completion and user confidence, though direct evidence is still limited. This approach works best for tasks where requirements are different each time, like legal advice or tax help. Early users say it keeps prompts short and focused, and may help the AI give more accurate answers.
Anthropic, IBM, and AWS Detail 5 Stages for AI Agent QA

Anthropic, IBM, and AWS Detail 5 Stages for AI Agent QA

Anthropic, IBM, and AWS describe a five-stage process for testing and validating AI agent software. This pipeline starts with automatic code checks during development and continues with automated and human evaluations before and after release. Canary deployments and ongoing monitoring may help catch issues that do not show up in pre-release tests. The process suggests collecting feedback from real incidents to improve tests over time, while governance policies and versioned datasets might help teams track changes and maintain quality. Some experts note that these controls may speed up delivery, but there might be initial slowdowns as teams adapt.

New research expands AI prompting from hacks to cognitive skill

New research expands AI prompting from hacks to cognitive skill

New research suggests that prompting AI is a thinking skill that comes from clear mental models, not just using tricks or hacks. Studies link good prompting to habits like breaking down tasks, predicting responses, and using the right context, which may help manage cognitive load. Early evidence hints that structured prompting training could make professionals faster and their AI outputs more useful, though more data is needed. Researchers also propose that treating prompting as a step-by-step dialogue, instead of a single question, may help people learn and use AI tools better.

LLM, RAG, AI Agents: What Each Means for Your AI Architecture

LLM, RAG, AI Agents: What Each Means for Your AI Architecture

LLM, RAG, AI agent, and Agentic AI are different ways to build AI systems, and picking the right one depends on the needs of the job. An LLM is best for simple tasks where no outside information or citations are needed. RAG may work better when answers need to include current or special documents, but its accuracy depends on what is found during retrieval. AI agents can handle tasks that require using tools or doing several steps, and Agentic AI may help when many agents need to work together on complex tasks. There may not be one best choice, so teams might start simple and add more features as their needs grow.

Engineering leaders adopt new AI ops for stable LLMs

Engineering leaders adopt new AI ops for stable LLMs

Engineering leaders say that writing good prompts alone may not guarantee stable results from language models, especially as users, models, and data change. Teams are starting to track all requests, monitor different metrics like quality and cost, and check for problems both automatically and with human reviews. Some suggest that only sampling part of the traffic and using guardrails may help contain costs and catch issues early. Experts recommend building systems that make it easier to switch between different AI providers without rewriting everything. Overall, prompt design is seen as just one part of a bigger process that includes ongoing testing, monitoring, and flexible system design.

LLM Memory: Developers Tackle Goldfish Memory With Hybrid Architectures

LLM Memory: Developers Tackle Goldfish Memory With Hybrid Architectures

Large language models (LLMs) are sometimes seen as forgetful, but the issue may actually be about where their memory is stored. The model's knowledge lives in frozen weights, while chat history and facts are kept outside in session context or databases. Developers use different strategies - like sliding windows, vector searches, and memory managers - to help LLMs remember more and work better. However, making LLMs handle bigger memories may raise costs and slow responses, so engineers carefully limit and manage what information is sent each time. Reports suggest that simply increasing context size does not always improve results, and hybrid systems are being developed to handle memory more effectively.

LLMs Gain Memory: New Techniques Extend Context Without Inflating Costs

LLMs Gain Memory: New Techniques Extend Context Without Inflating Costs

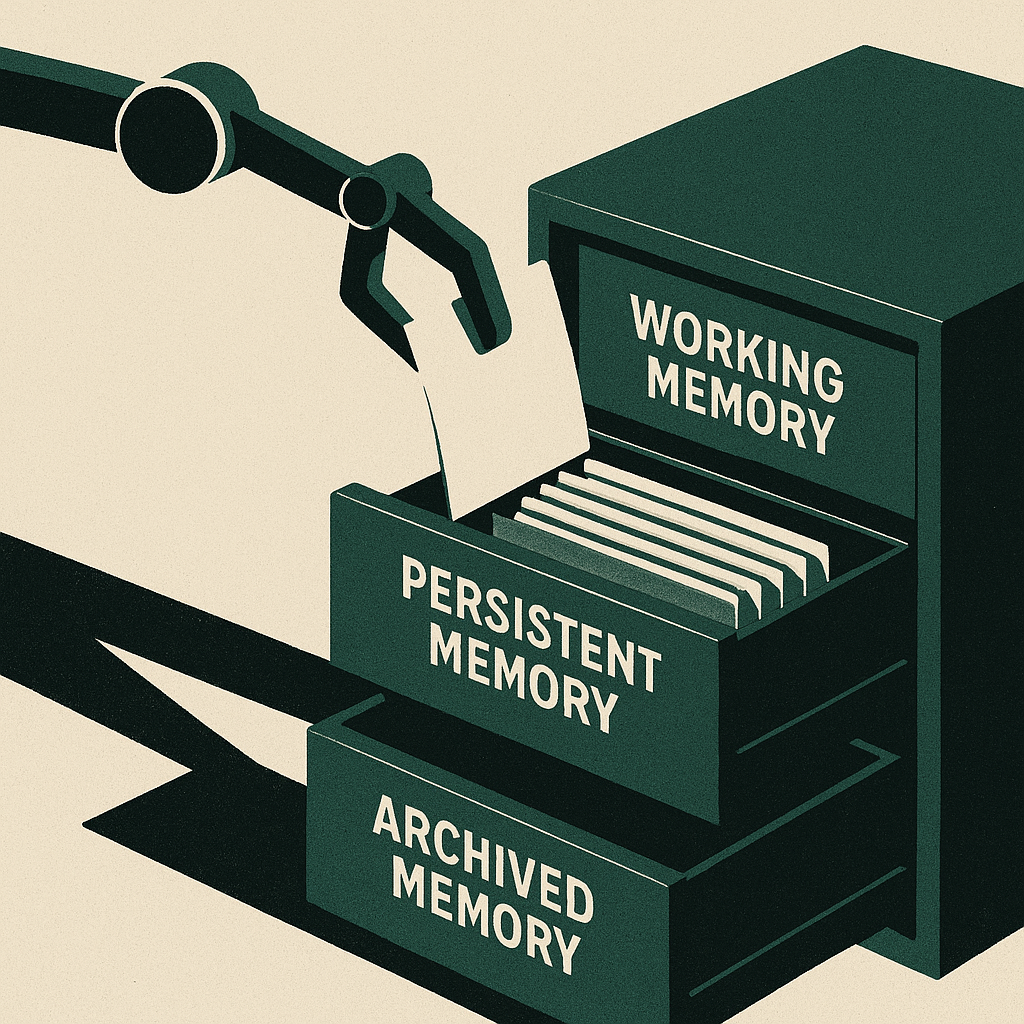
Recent studies suggest that large language models (LLMs) do not remember personal details between uses, so applications must repeat context for each turn. Engineers describe three layers of memory: trained memory (background knowledge), working memory (current context window), and persistent memory (external storage like databases). New techniques, like DeepSeek V4.1-Flash and Recurrent Looped Transformers, may make memory use more efficient without raising costs. Developers face choices between methods like sliding-window prompts, summarization, and retrieval-augmented generation, each with benefits and trade-offs. Researchers propose that combining efficient internal memory with structured external storage may allow LLMs to keep important information without high costs.

Vertical AI Firms Expand Data Moats With Longer Training Windows

Vertical AI Firms Expand Data Moats With Longer Training Windows

Vertical AI companies may make their data advantages stronger by using longer training windows and collecting unique signals from how customers use their products. Research suggests these firms build a hard-to-copy "data moat" when they turn everyday customer interactions into training data, which might improve their AI over time. Two main tests for a real data moat are whether the data is hard to reproduce within a year and if it clearly makes the product better. Continuous feedback from users appears to help teams measure and improve their models, and deeply integrated products may be harder for competitors to replace quickly. Publishing live product and data metrics may also help show the value of these data advantages to investors.

New 2026 Guide Details LLM Error Handling, Cost Control

New 2026 Guide Details LLM Error Handling, Cost Control

The new 2026 guide gives steps for handling errors and keeping costs low in LLM-powered apps. It suggests sorting errors into technical, semantic, and context-window types, and using retries, fallbacks, and human checks as needed. The guide says input should be checked before sending to the model, and all outputs should be validated for correctness. Cost control may be improved by saving tokens and caching prompts, which reportedly cuts expenses and speeds up response times. The best practices appear to help teams keep LLM systems reliable and affordable, while accepting that some uncertainty remains.

Zylos AI Report: How LLM Apps Use Layered Error Recovery in 2026

Zylos AI Report: How LLM Apps Use Layered Error Recovery in 2026

The Zylos AI report suggests that dealing with errors in large language model (LLM) apps often relies on a layered approach, where different types of errors are handled in different ways. Teams may classify problems as transient (temporary), permanent, or semantic (meaning-related), and respond based on this tagging. The report notes that retrying is suitable for transient issues, but not for permanent errors, while semantic mistakes like bad outputs need validation or repair. Recent work also suggests using fallback models, output checks, and collecting error traces to find patterns and improve systems. These steps may help teams spot, classify, and fix many types of errors found in LLM-powered apps.

Anthropic's Claude Cowork browser isolates sessions, blocks risky sites

Anthropic's Claude Cowork browser isolates sessions, blocks risky sites

Anthropic's Claude Cowork browser runs in a separate cloud space and does not access user tabs, bookmarks, or passwords. Each session is deleted when it ends, and risky sites like online banking and corporate email are blocked by default. Experts suggest that while safety checks help, hidden instructions on web pages may still trick the agent into leaking information. Anthropic warns that skipping approval steps can increase this risk, and human oversight remains important. The company recommends limiting browser permissions and making sure sensitive sites are not accessible by the agent.

Zylos.ai and FutureAgi Detail LLM Error Recovery Strategies for 2026

Zylos.ai and FutureAgi Detail LLM Error Recovery Strategies for 2026

Zylos.ai and FutureAgi describe strategies for handling errors in LLM-powered applications. They suggest that classifying errors into different types and responding to each type specifically may help avoid bigger problems. The reports recommend validating every step, retrying only some errors with careful limits, and using fallback models when needed. Full logging and traceability appear to help teams understand and fix failures. Both sources suggest that constant measurement and layered defenses might improve system reliability by 2026.

LLM Model Routing Cuts Costs Up To 70% in 2026

LLM Model Routing Cuts Costs Up To 70% in 2026

Smart Model Routing sends each query to the cheapest language model that still gives good enough results. Case studies suggest this can lower costs by as much as 70% if most requests are simple. Teams usually start with basic routing and strong safeguards, then move to more advanced methods as they gain confidence. Experts say savings depend on how many queries can use a cheaper model and that some complex tasks may not save as much. Guides recommend logging everything, using safety checks, and updating rules when new models become available.

Zylos AI outlines new GenAI error handling patterns for 2026

Zylos AI outlines new GenAI error handling patterns for 2026

Zylos AI suggests that handling errors in GenAI systems must go beyond technical faults to include problems like hallucinations and wrong outputs, which may not be obvious right away. Their guidance says that every step in an LLM request can have different issues, and each one may need its own way to recover. Teams now label errors as either transient, permanent, or semantic before deciding how to fix them. Common controls include retrying after short-term errors, switching to backup models after bad outputs, and validating every response. These methods appear to help make GenAI systems more stable and easier to manage, though improvements may still be ongoing.

LLM App Reliability: New 2026 Playbook Details Error Handling

LLM App Reliability: New 2026 Playbook Details Error Handling

The 2026 playbook for LLM-powered apps highlights that errors can happen even when API calls appear successful, so engineers treat every answer as untrusted until it passes checks. Failures may be technical, related to context limits, or semantic when outputs look fine but break business rules. Teams reportedly use layered controls like schema validation, retries, circuit breakers, fallbacks, and monitoring to catch and contain problems. Adding these controls, especially validating input and output, may boost success rates and help spot issues early. However, no method fully removes uncertainty, so these steps just make systems more reliable and easier to audit when errors appear.