AI Deep Dives & Tutorials
LLM Memory: Developers Tackle Goldfish Memory With Hybrid Architectures
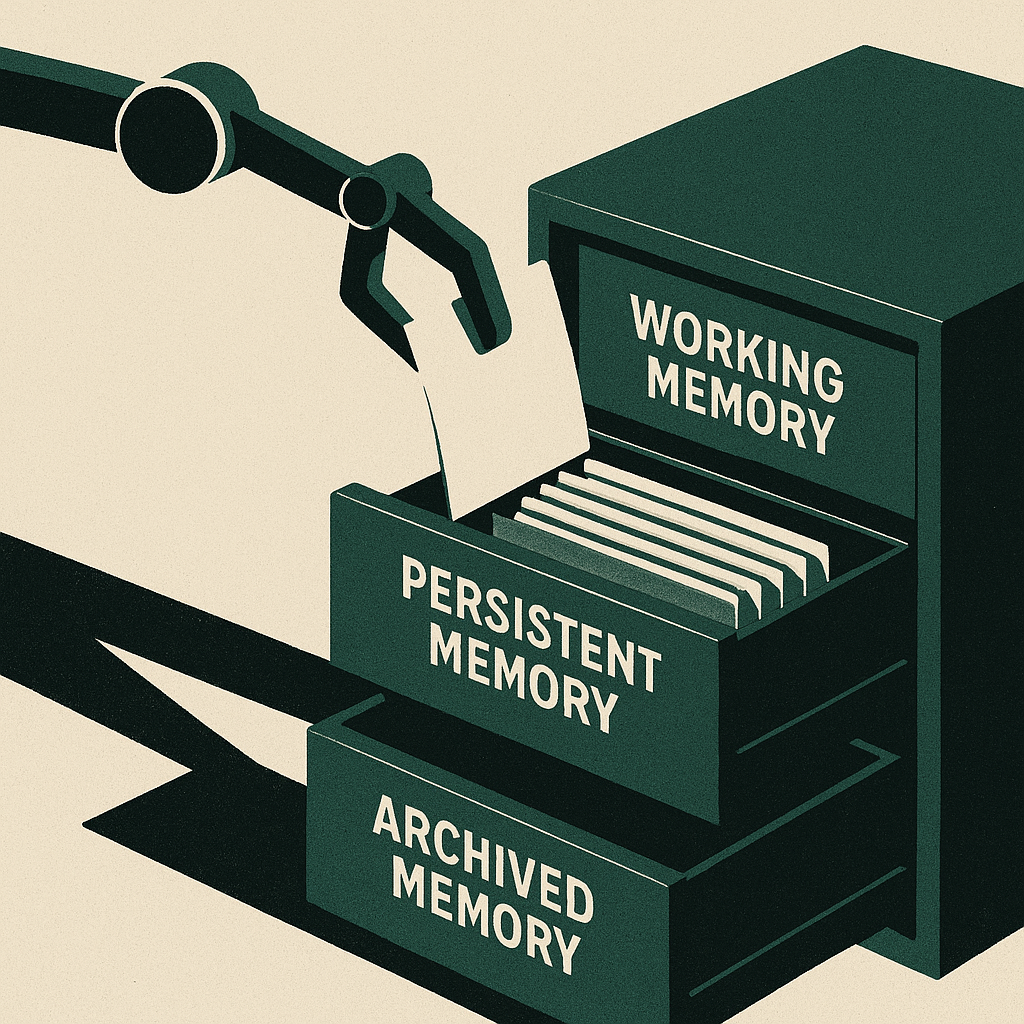
Large language models (LLMs) are sometimes seen as forgetful, but the issue may actually be about where their memory is stored. The model's knowledge lives in frozen weights, while chat history and facts are kept outside in session context or databases. Developers use different strategies - like sliding windows, vector searches, and memory managers - to help LLMs remember more and work better. However, making LLMs handle bigger memories may raise costs and slow responses, so engineers carefully limit and manage what information is sent each time. Reports suggest that simply increasing context size does not always improve results, and hybrid systems are being developed to handle memory more effectively.